GPU Cards
The compute heart of every accelerated system. We work across current accelerator generations — from data-center training GPUs to inference-optimized cards — matched to your model size, memory footprint and throughput targets.
HARDWARE & PLATFORMS / MCI WORLD
From GPU cards to cooling, storage to software — every layer of an compute infrastructure estate, specified and integrated as one system.
CATALOG
Each category below is a layer of a real accelerated deployment. Configurations, quantities and availability are confirmed with the team for every engagement.
The compute heart of every accelerated system. We work across current accelerator generations — from data-center training GPUs to inference-optimized cards — matched to your model size, memory footprint and throughput targets.
GPU-dense server platforms engineered for training and inference clusters. Rack-scale systems with high-speed interconnect, validated thermals and remote management for production estates.
Desk-side accelerated systems for data science, model development, simulation and design teams — enterprise GPUs with workstation reliability, before workloads graduate to the cluster.
Host processors that feed the accelerators. Core count, memory channels and I/O lanes are balanced against the GPU count so the host never starves the compute.
System memory and HBM configurations sized for large models and datasets. Memory capacity and bandwidth often decide what a GPU can actually deliver — we size it deliberately.
The fabric that turns servers into a cluster. High-speed NICs and SuperNICs with RDMA keep multi-node training synchronized and inference latency low.
Data processing units offload networking, storage and security work from the CPU, while PCIe topology and GPU-to-GPU interconnect define how fast data moves inside each node.
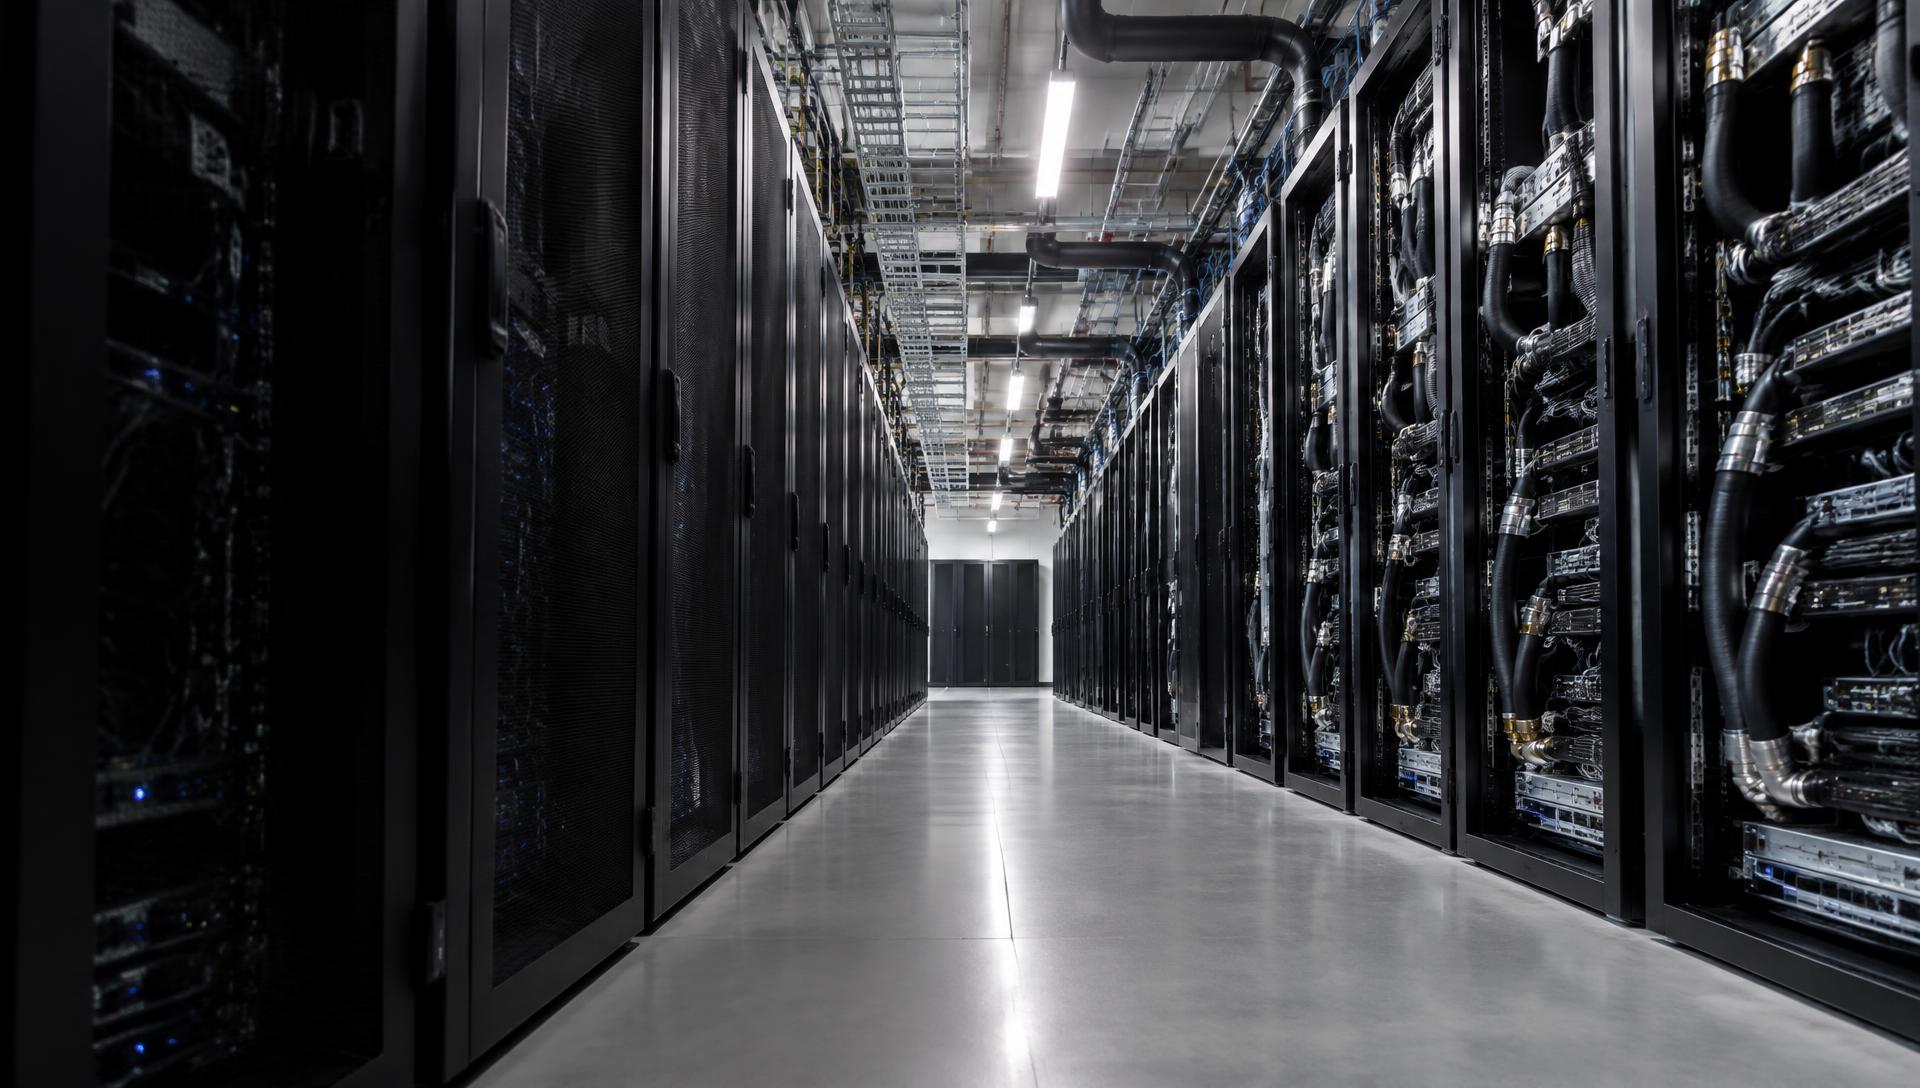
High-density compute racks demand engineered cooling — air, liquid or hybrid — and power distribution designed for sustained accelerator load, not nameplate averages.
Training data, checkpoints and model artifacts need fast, resilient storage. From NVMe-local to parallel file systems, sized to keep GPUs fed instead of waiting.
Inference where the data is born. Ruggedized and embedded compute modules for factories, vehicles, defense platforms and remote sites — connected back to the core when needed.
The stack above the metal: orchestration, model frameworks, MLOps tooling, monitoring and security — so hardware capacity becomes usable, governed computing capability.
We source and integrate across leading original equipment and design manufacturers, selecting the right platform partner for each build rather than forcing a single vendor.
NEXT STEP
Tell us the workload and we will come back with an indicative configuration across these layers.